Showing posts with label BWA-MEM. Show all posts

Saturday, August 10, 2019

Disqus / Twitter Follow-Up: Comparing My 23andMe SNP Chip Concordance with Different Veritas WGS files

I am mostly summarizing my points from the following Twitter discussion:

https://twitter.com/carolinefwright/status/1157219572514209792

The original intention was to add this as a comment in the Disqus comment in the original pre-print discussion.  However, I thought this was fairly long, and I wanted to be able to have a little more control over figure formatting.

For reference, I recommended taking a look at Illumina arrays in an earlier comment, and I mentioned there there are datasets with both 23andMe SNP chip data and high-throughput sequencing data (like myself).

As a success story, that comment was followed up on, and new data was added.  In particular, there was a plot of the error/discordance rate between my own 23andMe data and my Veritas WGS data posted on Twitter.

I think this is great, but I think it may be worth emphasizing that re-processing my Veritas WGS data resulted in better concordance with my Exome data.  Additionally, I have an upgraded V5 chip, so there are actually 2 sets of 23andMe Data (although almost all of these results are based upon my later set of V3_V5 genotypes).

Nevertheless, I actually have 2 .vcf files for my Veritas WGS data (the provided .vcf, and the .vcf that I produced from extracted FASTQ files and reprocessed using BWA-MEM and GATK).

I did some analysis with my V3 23andMe genotypes, but I think that was mostly consistent with my V3_V5 genotypes.  Among probes on both arrays, there were only 5 discordant sites (so, I think that is how the previously lower error rate was reported: SNP chip versus same SNP chip, instead of SNP chip versus WGS).

In contrast, even the best-case scenario for my data seems to have concordance of 97.6-99.2% (with MAF > 0.01 variants), and this was slightly lower for the V3_V5 genotypes.  If I only considered my original V3 genotypes, this would have been better than I had previously reported for my Exome versus WGS data (98-99% for BWA-MEM + GATK re-processed variants).  However, either way, there are over a million probes on the V5 23andMe array.  So, I think something about variants being used for “research purposes” may be relevant (although I will show below that certain sets of variants do have higher reproducibility).

The trends can vary depending upon what I use for the MAF calculation:

1000 Genomes:


gnomAD:


Kaviar:


I am showing 2 plots each because I have 2 .vcf files for my WGS data (the one provided by Veritas, and the BWA-MEM + GATK re-processed variant file).  While the results are above are mostly similar with either Veritas WGS .vcf, there are some noticeable differences in the exact set of rare variants with different population estimates (which could either be because of the composition of individuals, or with the different sample processing strategies for each project).

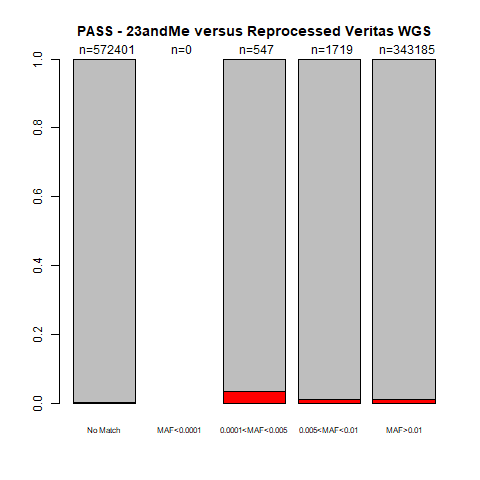
When I converted my 23andMe to VCF format, I added a “PASS” status (to keep track of variants within repeats, for example).  If there was no other note, the variant had a “PASS” in the FILTER column.  If I only consider “PASS” variants, this is what those plots look like:

1000 Genomes:


gnomAD:


Kaviar:


If I only consider the “PASS” variants, the accuracy also increases a little (from 98.8-99.7% for my initial V3 genotypes, and 98.009-99.997% with the range of MAF for my V3_V5 genotypes), usually in the far-left column.

Finally, if I start from the full set of variants, but I only look at those that were discordant between my WGS .vcf files, I see better concordance for re-processed variants if they are common (but the trend for the smaller variant sets can vary):

1000 Genomes:


gnomAD:


Kaviar:


For these plots, the largest number of variants are in the far-right column.  Since that far-right column usually has less SNP chip discordance (less red in the barplot), that is consistent with my earlier conclusion that re-processing the WGS data could produce variants with higher overall concordance (in that situation, between Exome and WGS data).  However, this can clearly vary between individual variants/positions (and the best processing strategy may vary depending upon where you need to be calling variants).

I can't really visualize the SNP chip data, and I kind of have to trust the "NC" status for "No Call" positions (and I don't have access to a more raw form of data, like the intensities).

However, as a general rule, I would always recommend checking your alignments for false negatives or false positives (which you can do with a free genome browser like IGV).  I added some ClinVar annotations to try and find some discordant sites to check, and I've listed a couple below:

1) I was surprised that my re-processed was missing my cystic fibrosis variant (which I have a whole other post about).  However, this was purely a formatting issue.

Namely, I threw out most indel positions (indicated by DI) because figuring out exactly what that represents is more difficult than for the SNPs.  However, with my earlier V3 chip analysis, I manually converted some indels in my code (including my cystic fibrosis indel).  However, I converted to match the freebayes indel format in the provided .vcf for the .

In the other blog post, you can clearly see that I am a cystic fibrosis carrier, even with the re-alignment.  So, I looked up the GATK format for that indel and checked the status of that variant.  Indeed, I do have a variant call for chr7 117149181 . CTT C.  So, this is in fact OK (as long as the annotation software can figure out I have the variant, which I think was part of the problem described in the other blog post).

2) While it wasn't a discordant site between .vcf files, there were only a limited number of total ClinVar pathogenic variants.  So, I happened to notice one that indicated I was homozygous for the pathogenic variant in my 23andMe data (1/1) but a variant was not called at that position with either of the Veritas WGS .vcf files (indicated by a 0/0 in the genotype columns).  In other words, the SNP chip data was consistent with a SNP chip replicate, the WGS variant was robust different processing methods, but the result was different for SNP chip versus WGS.

However, I can check the alignments for both the provided and reprocessed WGS data (as well as provided and reprocessed Exome data), which is what I do below:


The plot above shows alignments in the following order (top to bottom): Genos Exome Provided, Genos Exome Reprocessed, Veritas WGS Provided, Veritas WGS Reprocessed

So, from the alignments, I would be inclined to agree with the WGS variant calls.  If there is some isoform of the gene that is so far diverged the reads wouldn't align, that could be an exception.  However, I don't think that situation would be best described as a SNP.  Also, I don't believe any reports indicated that I had predisposition to Neurofibromatosis (and I don't know anybody in my family that was diagnosed with that disease).  This was a custom 23andMe probe (labeled as i5003284, instead of a typical rsID).  However, the larger ANNOVAR annotation file has the ClinVar information, and I can find a dbSNP ID using the UCSC Genome Browser (for hg19, chr17:29541542).  So, in terms of checking the ANNOVAR annotation, if I actually did have two copies of an NF1 pathogenic variant, rs137854557 does have multiple reports indicating it being pathogenic (less of a confident assertion than my cystic fibrosis variant, but more than most of my other "pathogenic" variants).

As a final note, the data and code for analysis of my V3_V5 23andMe genotype data (and 2 Veritas WGS .vcf files) is available here.

Update Log:

8/10/2019 - public post date
1/15/2020 - add tag for "Converted Twitter Response"

Sunday, August 4, 2019

Predicting HLA Types for Array and High-Throughput Sequencing Data

My previous link to my HLA-assignments with varying technologies has the most important table in the middle of the page.  So, I am mostly reproducing that here to make the information easier to view.


SNP2HLA HIBAG bwakit HLAminer
HLA-A A*01, A*02
(23andMe)

A*01, A*02
(Genes for Good)

A*01, A*02
(AncestryDNA)
A*01, A*02
(23andMe)

A*01, A*02
(AncestryDNA)
A*01, A*02
(Genos Exome BWA-MEM)
A*01, A*02
(Genos Exome BWA-MEM)

A*01, A*68
(Genos Exome BWA)
HLA-B B*08, B*40
(23andMe)

B*08, B*40
(Genes for Good)

B*08, B*40
(AncestryDNA)
B*08, B*40
(23andMe)

B*08, B*40
(AncestryDNA)
B*08, B*40
(Genos Exome BWA-MEM)
B*08, B*40
(Genos Exome BWA-MEM)

B*08, B*41
(Genos Exome BWA)
HLA-C C*03, C*07
(23andMe)

C*03, C*07
(Genes for Good)

C*03, C*07
(AncestryDNA)
C*03, C*07
(23andMe)

C*03, C*07
(AncestryDNA)
C*03, C*07
(Genos Exome BWA-MEM)
C*03, C*07
(Genos Exome BWA-MEM)

C*03, C*07
(Genos Exome BWA)
HLA-DRB1 DRB1*01, DRB1*03
(23andMe)

DRB1*01, DRB1*03
(Genes for Good)

DRB1*01, DRB1*03
(AncestryDNA)
DRB1*03, DRB1*11
(23andMe)

DRB1*03, DRB1*15
(AncestryDNA)
DRB1*04, DRB1*04
(Genos Exome BWA-MEM)
DRB1*01, DRB1*15
(Genos Exome BWA-MEM)

DRB1*01, DRB1*15
(Genos Exome BWA)
HLA-DQA1 DQA1*05, DQA1*05
(23andMe)

DQA1*01, DQA1*05
(Genes for Good)

DQA1*01, DQA1*05
(AncestryDNA)
DQA1*05, DQA1*05
(23andMe)

DQA1*01, DQA1*05
(AncestryDNA)
DQA1*03, DQA1*03
(Genos Exome BWA-MEM)
DQA1*02, DQA1*03
(Genos Exome BWA-MEM)

DQA1*02, DQA1*03
(Genos Exome BWA)
HLA-DQB1 DQB1*02, DQB1*05
(23andMe)

DQB1*02, DQB1*02
(Genes for Good)

DQB1*02, DQB1*05
(AncestryDNA)
DQB1*02, DQB1*03
(23andMe)

DQB1*03, DQB1*06
(AncestryDNA)
DQB1*03, DQB1*03
(Genos Exome BWA-MEM)
DQB1*02, DQB1*03
(Genos Exome BWA-MEM)

DQB1*02, DQB1*03
(Genos Exome BWA)

In other words, my HLA-A / HLA-B / HLA-C types could be identified more robustly than the HLA-D genotypes (which I don't know, since I haven't gotten a regular blood test).  However, my understanding is that those types have a greater priority in defining organ transplant matches (although I'm currently encountering some difficulty finding the reference for that).

The GitHub link also goes a little deeper into how 23andMe is using 2 SNPs to represent 2 haplotypes (across genes) for celiac disease (which I found surprising, but that is done for other diagnostics as well).  I am mostly leaving that out of this section, but I did think it was interesting that HLA was used in 23andMe's "Meet Your Genes" when the SNPs are actually intronic / intergenic (with respect to the RefSeq annotations).

My 23andMe report indicated that I was DQ8-positive but DQ2-negative for my celiac disease risk.  In terms of defining the 2 genes used to define my DQ8-positive status I coloring matching assignments above in magenta (HLA-DQA1*03 and HLA-DQB1*0302).

Here is a screenshot for the variants tested by 23andMe (where I have the "C" variant for rs7454108, for the marker described as "HLA-DQ8"):


Again, as described here, a positive HLA-DQ8 status is defined by having HLA-DQA1*03 and HLA-DQB1*0302.

More recently, I collected Illumina Whole Genome Sequencing data where unaligned reads were provided (from Sequencing.com), along with some amount of PacBio HiFi data from Dante Labs.  There are some parts of the results that are not especially clear to me and I am interested to learn about additional options for analysis.  However, I believe those results are consistent with me having at least one DQB1*03 allele.

In terms of what appears to be consistent between the PacBio data and Illumina Whole Genome Sequencing data, the T1K results from the Sequencing.com Illumina reads indicates that the related HLA-DQB1 allele should be HLA-DQB1*03:02:01.

I ordered additional GlutenID testing from Targeted Genomics, with an uploaded subfolder on GitHub.  However, I believe the potential problem with using this for validation is that the DQ8-DQ8 result is based upon the same 1 SNP as my 23andMe result (rs7454108).  So, I will continue to look into additional validation options.

I am interested to learn more about the broader trends if certain HLA types are harder to assign and/or impute than other HLA types.  I have some notes mentioned in this Disqus comment.  Comments containing relevant feedback is also welcome on this blog post.

Update Log:

8/4/2019 - public post date
8/6/2019 - minor changes
8/15/2019 - add coloring for HLA-DQ8
2/11/2024 - add information / links to Whole Genome Sequencing data (Illumina from Sequencing.com and PacBio HiFi from Dante Labs)
2/18/2024 - add screenshot from 23andMe + dbSNP link; add additional HLA-DQ8 sentence; add small paragraph for Illumina WGS T1K result; add link to Disqus comment; fix minor typos + add tags
2/27/2024 - minor change in column header
3/19/2024 - minor change in column header; add link to GlutenID results

Saturday, May 4, 2019

precisionFDA and Custom Scripts for Variant Comparisons

After posting this reply to a tweet, I thought it might be a good idea to separate some of the points that I was making about comparing genotypes for the same individual (from this DeepVariant issue thread).

For those who might not know, precisionFDA provides a way to compare and re-analyze your data for free.  You need to create an account, but I could do so with a Gmail address (and an indication that you have data to upload).  I mostly show results for comparing .vcf files (either directly provided from different companies, or created via command line outside of precisionFDA).

I needed to do some minor formatting with the input files, but I provided this script to help others to the same.  I also have another script that I was using to compare .vcf files.

For the blog post, I'll start by describing the .vcf files provided from the different companies.  If readers are interested, I also have some messy notes in this repository (and subfolders), and I have raw data and reports saved on my Personal Genome Project page.

For example, this is the results for the SNPs from my script (comparing recovery of variants in my Genos Exome data within my Veritas WGS data):

39494 / 41450 (95.3%) full SNP recovery
39678 / 41450 (95.7%) partial SNP recovery

My script also compares indels (as you'll see below), but I left that out this time (because Veritas used freebayes, and I didn't convert between the two indel formats).

I defined "full" recovery as having the same genotype (such as "0/1" and "0/1", for a variant called as heterozygous by both variant callers).  I defined  "partial" recovery as having the same variant, but with a different zygosity (so, a variant at the same position, but called as "0/1" in one .vcf but called as "1/1" in the other .vcf would be a "partial" recovery but not a "full" recovery).

You can also see that same comparison in precisionFDA here (using the RefSeq CDS regions for the target regions), with a screenshot shown below:


So, I think these two strategies complement each other in terms of giving you slightly different views about your dataset.

If I re-align my reads with BWA-MEM and call variants with GATK (using some non-default parameters, like removing soft-clipped bases; similar to shown here, for Exome file, but not WGS, and I used GATK version 3.x instead of 4.x) and filter for high-quality reads (within target regions), these are what the results look like (admittedly, using an unfiltered set of GATK calls to test recovery in my WGS data):

Custom Script:

20765 / 21141 (98.2%) full SNP recovery
20872 / 21141 (98.7%) partial SNP recovery
243 / 258 (94.2%) full insertion recovery
249 / 258 (96.5%) partial insertion recovery
208 / 228 (91.2%) full deletion recovery
213 / 228 (93.4%) partial deletion recovery

precisionFDA:


Since I was originally describing DeepVariant, I'll also show those as another comparison using re-processed data (with variants called from a BWA-MEM re-alignment):

Custom Script:

51417 / 54229 (94.8%) full SNP recovery
53116 / 54229 (97.9%) partial SNP recovery
1964 / 2391 (82.1%) full insertion recovery
2242 / 2391 (93.8%) partial insertion recovery
2058 / 2537 (81.1%) full deletion recovery
2349 / 2537 (92.6%) partial deletion recovery

precisionFDA:


So, one thing that I think is worth pointing out is that you can get better concordance if you re-process the data (although the relative benefits are a little different for the two strategies provided above).

Also, in terms of DeepVariant, I was a little worried about over-fitting, but that was not a huge issue (I think it was more like an unfiltered set of GATK calls, but requiring more computational resources).  Perhaps that doesn't sound so great, but I think it is quite useful to the community to have a variety of freely available programs; for example, if DeepVariant happened to be a little better at finding the mutations for your disease, that could be quite important for your individual sample.  Plus, I got a $300 Google Cloud credit, so it was effectively free for me to use on the cloud.

As a possible point of confusion, I am encouraging people to use precisionFDA to compare (and possibly re-analyze) new data.  However, there was also a precisionFDA competition.  While I should credit DeepVariant to cause me to test out the precisionFDA interface, my opinion is that the ability to make continual comparisons may actually be more important than that competition from a little while ago.  For example, I think different strategies with high values should be comparable (not really one being a lot better than the others, as might be implied from having a "winner"), and it should be noted that that competition focused on regions where "they were confident they could call variants accurately"  Perhaps that explains part of why the metrics are higher than my data (within RefSeq CDS regions)?  Plus, I would encourage you to "explore results" for that competiation to see statistics for subsets of variants, where I think the func_cds group may be more comparable to what I performed (or at least gives you an idea of how rankings can shuffle with a subset of variants that I would guess are more likely to be clinically actionable).
 
Creative Commons License
Charles Warden's Science Blog by Charles Warden is licensed under a Creative Commons Attribution-NonCommercial-NoDerivs 3.0 United States License.